
Iterable Core (v2)
Last updated: 9/15/2026This integration is powered by Singer's Iterable tap and certified by Stitch. Check out and contribute to the repo on GitHub.
For support, contact Support.
Iterable integration summary
Stitch’s Iterable integration replicates data using the Iterable API 1.8. Refer to the Schema section for a list of objects available for replication.
Iterable feature snapshot
A high-level look at Stitch's Iterable (v2) integration, including release status, useful links, and the features supported in Stitch.
| STITCH | |||
| Release status |
Released on June 22, 2026 |
Supported by
|
|
|
Stitch plan
|
Standard |
API availability
|
Available
|
| Singer GitHub repository | |||
| REPLICATION SETTINGS | |||
|
Anchor Scheduling
|
Supported
|
Advanced Scheduling
|
Supported
|
|
Table-level reset
|
Unsupported
|
Configurable Replication Methods
|
Unsupported
|
| DATA SELECTION | |||
|
Table selection
|
Supported
|
Column selection
|
Supported
|
|
Select all
|
Supported
|
||
| TRANSPARENCY | |||
|
Extraction Logs
|
Supported
|
Loading Reports
|
Supported
|
Connecting Iterable
Iterable setup requirements
To set up Iterable in Stitch, you need:
-
You must be an org admin or a user with API and Webhook configuration permissions in your Iterable account.
Step 1: Generate an Iterable API key
- Sign into you Iterable account.
- Navigate to Integrations>API Keys.
- Click New API Key.
- In the Create a new API key window, name your API key and select read-only.
- Click Create.
- Copy your new API key and have it ready for the next step.
Step 2: Add Iterable as a Stitch data source
- Sign into your Stitch account.
-
On the Stitch Dashboard page, click the Add Integration button.
-
Click the Iterable icon.
-
Enter a name for the integration. This is the name that will display on the Stitch Dashboard for the integration; it’ll also be used to create the schema in your destination.
For example, the name “Stitch Iterable” would create a schema called
stitch_iterablein the destination. Note: Schema names cannot be changed after you save the integration. - In the Iterable API Key field, paste the API key you copied in step 1.
- In the API Window in Days field, enter a value. This parameter should be set to an optimum value to improve historical sync performance. Setting this value too low will take longer to complete historical sync and setting it larger may result in request timeouts or memory overflow issues.
Step 3: Define the historical replication start date
The Sync Historical Data setting defines the starting date for your Iterable integration. This means that data equal to or newer than this date will be replicated to your data warehouse.
Change this setting if you want to replicate data beyond Iterable’s default setting of 1 year. For a detailed look at historical replication jobs, check out the Syncing Historical SaaS Data guide.
Step 4: Create a replication schedule
In the Replication Frequency section, you’ll create the integration’s replication schedule. An integration’s replication schedule determines how often Stitch runs a replication job, and the time that job begins.
Iterable integrations support the following replication scheduling methods:
-
Advanced Scheduling using Cron (Advanced or Premium plans only)
To keep your row usage low, consider setting the integration to replicate less frequently. See the Understanding and Reducing Your Row Usage guide for tips on reducing your usage.
Step 5: Set objects to replicate
The last step is to select the tables and columns you want to replicate. Learn about the available tables for this integration.
Note: If a replication job is currently in progress, new selections won’t be used until the next job starts.
For Iterable integrations, you can select:
-
Individual tables and columns
-
All tables and columns
Click the tabs to view instructions for each selection method.
- In the integration’s Tables to Replicate tab, locate a table you want to replicate.
-
To track a table, click the checkbox next to the table’s name. A blue checkmark means the table is set to replicate.
-
To track a column, click the checkbox next to the column’s name. A blue checkmark means the column is set to replicate.
- Repeat this process for all the tables and columns you want to replicate.
- When finished, click the Finalize Your Selections button at the bottom of the screen to save your selections.
- Click into the integration from the Stitch Dashboard page.
-
Click the Tables to Replicate tab.
- In the list of tables, click the box next to the Table Names column.
-
In the menu that displays, click Track all Tables and Fields:
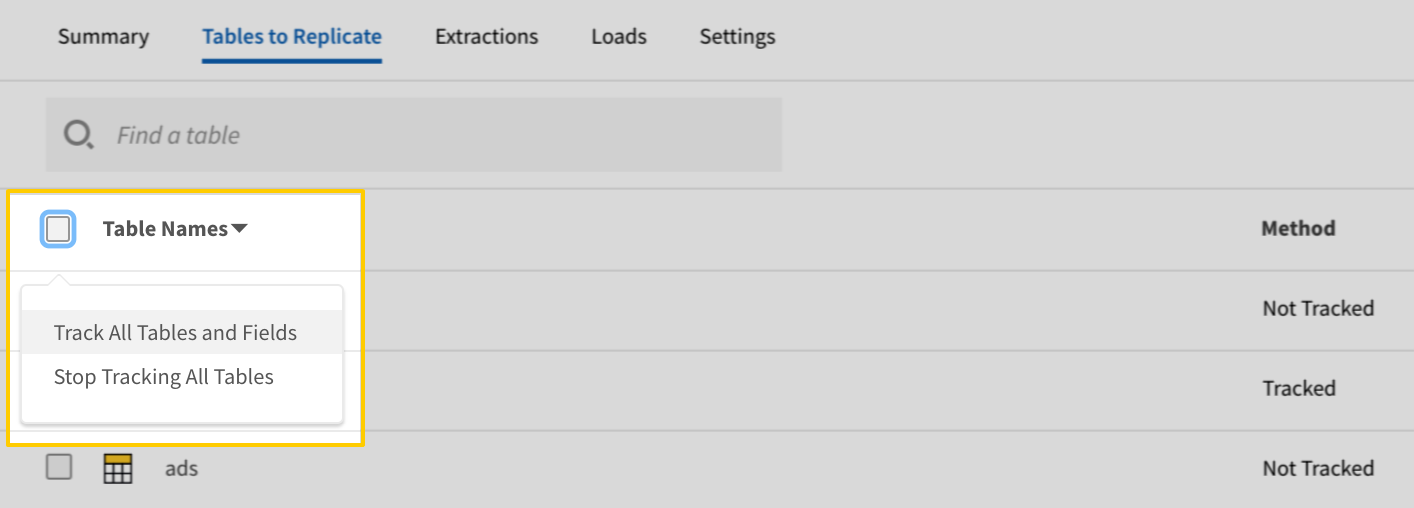
The Track all Tables and Fields menu in the Tables to Replicate tab - Click the Finalize Your Selections button at the bottom of the page to save your data selections.
Initial and historical replication jobs
After you finish setting up Iterable, its Sync Status may show as Pending on either the Stitch Dashboard or in the Integration Details page.
For a new integration, a Pending status indicates that Stitch is in the process of scheduling the initial replication job for the integration. This may take some time to complete.
Initial replication jobs with Anchor Scheduling
If using Anchor Scheduling, an initial replication job may not kick off immediately. This depends on the selected Replication Frequency and Anchor Time. Refer to the Anchor Scheduling documentation for more information.
Free historical data loads
The first seven days of replication, beginning when data is first replicated, are free. Rows replicated from the new integration during this time won’t count towards your quota. Stitch offers this as a way of testing new integrations, measuring usage, and ensuring historical data volumes don’t quickly consume your quota.
Iterable table reference
Schemas and versioning
Schemas and naming conventions can change from version to version, so we recommend verifying your integration’s version before continuing.
The schema and info displayed below is for version 2 of this integration.
This is the latest version of the Iterable integration.
Table and column names in your destination
Depending on your destination, table and column names may not appear as they are outlined below.
For example: Object names are lowercased in Redshift (CusTomERs > customers), while case is maintained in PostgreSQL destinations (CusTomERs > CusTomERs). Refer to the Loading Guide for your destination for more info.
campaigns
The campaigns table contains information about campaigns in your Iterable projcect.
|
Key-based Incremental |
|
|
Primary Key |
id |
|
Replication Key |
updatedAt |
| Useful links |


channels
The channels table contains information about all channels within your Iterable project.
|
Full Table |
|
|
Primary Key |
id |
| Useful links |
email_bounce
The email_bounce table contains information about bounced emails within your Iterable campaign.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_click
The email_click table contains information about clicks on your Iterable email campaign.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_complaint
The email_complaint table contains information about email recipients that sent complaints for your Iterable campain.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_open
The email_open table contains information about email recipients that opened your Iterable campaign.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_send
The email_send table contains information about campaign emails you sent in your Iterable account.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_send_skip
The email_send_skip table contains information about campaign email recipients that were skipped in your Iterable account.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_subscribe
The email_subscribe table contains information about emails subscribed to your Iterable campaign.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
email_unsubscribe
The email_unsubscribe table contains information about emails unsubscribed from your Iterable campaign.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
createdAt |
| Useful links |
list_users
The list_users table contains information about users in a list in your Iterable account.
|
Full Table |
|
|
Primary Keys |
listId |
| Useful links |
lists
The lists tablecontains information about lists within your Iterable project.
|
Full Table |
|
|
Primary Key |
id |
| Useful links |
message_types
The message_types table contains information about all message types within your Iterable project.
|
Full Table |
|
|
Primary Key |
id |
| Useful links |
metadata
The metadata table contains the metadata for a single key in your Iterable account.
|
Full Table |
|
|
Primary Key |
key |
| Useful links |
templates
The templates table contains information about project templates in you Iterable account.
|
Key-based Incremental |
|
|
Primary Key |
templateId |
|
Replication Key |
updatedAt |
| Useful links |
users
The users table contains information about all users in your Iterable account.
|
Key-based Incremental |
|
|
Primary Key |
|
|
Replication Key |
profileUpdatedAt |
| Useful links |